AI
Every AI feature eventually gets a bill review, and the first instinct is usually to swap models or shorten prompts. That is the expensive way to solve the problem. In most production systems the money is not leaking through pricing — it is leaking through redundancy. The same summary gets generated forty times because forty people clicked the same button. A trending article gets "Summarize"-ed by fifty users in the same thirty seconds, and your backend fans out fifty parallel upstream calls, each one paying full price and each one waiting for the slowest token.
Provider-level prompt caching (automatic prefix caching on OpenAI, explicit cache_control breakpoints on Anthropic) helps with repeated prefixes, but it does not deduplicate identical full requests at the application layer, and it does nothing about a concurrency stampede. Those are your problems to solve, and they are solvable in a few hundred lines.
Use this checklist as a gate before shipping any high-volume LLM route. Each item has a pass condition and a fail condition. Count your passes at the end.
Section 1 — Deterministic Request Identity
Figure: Editorial context image from the source page (preview only; rights remain with the publisher) · Credit / further reading: dev.to
If two logically identical requests can produce two different cache keys, nothing downstream matters. Determinism is the foundation.
1.1 Canonical serialization. Build the request payload through a canonical serializer, not JSON.stringify on a hand-built object.
- PASS: Key order is normalized, arrays are sorted where order is semantically irrelevant, whitespace is trimmed, and the resulting string is byte-identical across processes and deploys.
- FAIL: Your key changes when a dependency bumps its object property order, and hit rate silently collapses to zero.
1.2 Hash the full request tuple, not the user message. The hash input must include model ID, system prompt, temperature, top_p, top_k, max_tokens, stop sequences, tool/function schemas, response format, and seed if supported.
- PASS: Changing temperature from 0.2 to 0.9 produces a different key.
- FAIL: Hashing only the user content means a creativity-tuned call can be served a cached deterministic answer — a correctness bug disguised as a cost win.
1.3 Separate tenant and permission scope. Include workspace or organization ID in the key namespace.
- PASS: Two tenants submitting the same question never share a cache entry.
- FAIL: Cross-tenant hits — that is a data leak, not an optimization.
1.4 Version your prompts and schemas. Embed a prompt version string and tool-schema version in the key.
- PASS: Editing a system prompt in a deploy produces a clean cache namespace and the old entries age out.
- FAIL: You ship a prompt fix and users keep getting yesterday's behavior with no way to explain it.
1.5 Quarantine volatile inputs. Timestamps, request IDs, session tokens, and random seeds passed into the prompt will destroy hit rate.
- PASS: You either bucket volatile values to a coarse granularity (date instead of millisecond), strip them from the key, or consciously accept a near-zero hit rate for that route.
- FAIL: A
current_timefield in the system prompt means every request is unique and the cache is decorative.
Section 2 — What the Cache Stores
2.1 Store the assembled result, not the stream chunks. Persist the final text plus finish_reason, model version, token usage, and the tool-call trace if any.
- PASS: A cache hit can be replayed to the client as a synthetic stream so the UI contract is unchanged.
- FAIL: You cache raw SSE frames and the replayed stream breaks on any client that expects a specific chunk shape.
2.2 Never cache errors, refusals, or truncated output.
- PASS: Upstream 429s, timeouts, and
finish_reason: lengthresponses bypass the write path. - FAIL: A transient provider incident gets pinned into your cache for the full TTL and every user sees the failure.
2.3 TTL by content volatility, not one global value. Ticket classification can live for hours; news summarization should expire in minutes.
- PASS: TTL is configured per route with a documented rationale.
- FAIL: A single 24-hour default means stale answers on time-sensitive routes and wasted storage on stable ones.
2.4 Bound the store and define eviction.
- PASS: Entry count and byte size are capped with an LRU or TTL-sweep policy, and you can measure the eviction rate.
- FAIL: Unbounded in-memory map that grows until the process restarts.
Section 3 — In-Flight Coalescing (Single-Flight)
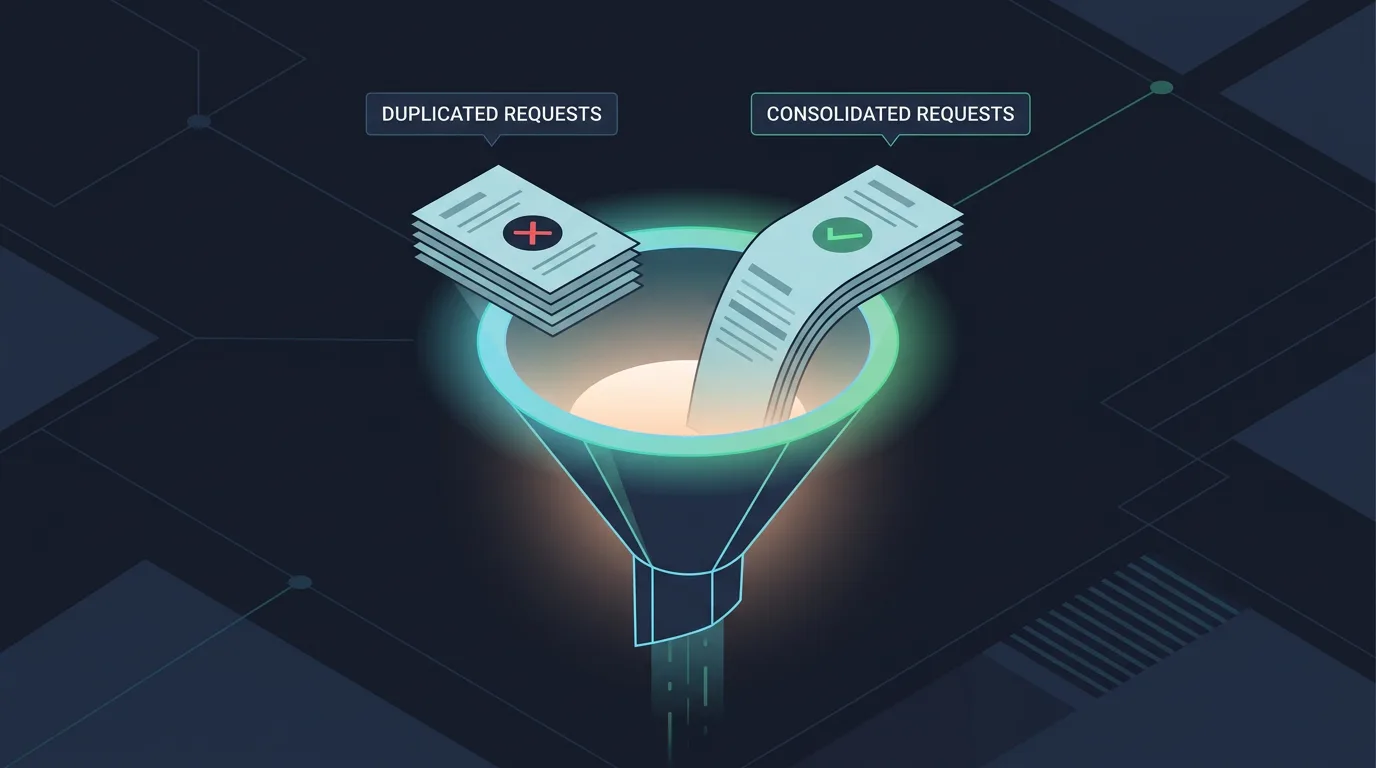
Figure: HEXOPS original illustration inspired by the topic (not a copy of the source article imagery) · Credit / further reading: dev.to
Caching handles the second request. Coalescing handles the second request that arrives while the first is still running — which is exactly the burst case.
3.1 Join concurrent identical calls. When a request arrives with a key already in flight, attach it to the pending promise instead of firing a new upstream call.
- PASS: Fifty simultaneous summarize requests produce one upstream call and fifty subscribers.
- FAIL: Fifty upstream calls, fifty invoices, and p95 latency set by the slowest of fifty.
3.2 Enforce an authorization check before joining.
- PASS: Coalescing happens only within the same tenant and permission scope, or after re-verifying the joined caller is entitled to that exact payload.
- FAIL: Joining across users because the key matched — a subtle privilege escalation.
3.3 Cap the fan-in.
- PASS: A maximum waiter count and a wait timeout exist; late arrivals fall back to cache or a fresh call.
- FAIL: One hung upstream request stalls every caller attached to it with no backpressure.
3.4 Exclude agentic and side-effecting loops.
- PASS: Multi-step tool-calling chains and any route that writes state are explicitly opted out of coalescing.
- FAIL: Two subscribers receive one execution's side effects, or a retry silently reuses a half-finished plan.
3.5 Keep usage accounting honest.
- PASS: Token cost is attributed once to the originator and recorded as saved cost for the joiners, so your unit economics stay readable.
- FAIL: Costs vanish from the ledger and no one can prove the optimization worked.
Section 4 — Observability and Governance
4.1 Instrument four numbers per route: cache hit rate, coalesced request count, estimated spend avoided, and p95 latency split by hit versus miss.
- PASS: A dashboard answers "what did we save last week" in one glance.
- FAIL: You are optimizing on vibes.
4.2 Log the hashed key, never the raw prompt.
- PASS: Debug logs carry a key prefix and route name, with prompt text excluded.
- FAIL: PII lands in log storage as a side effect of caching.
4.3 Ship a kill switch and an invalidation path.
- PASS: A flag disables caching and coalescing per route in seconds, and a version bump invalidates a namespace without manual deletion.
- FAIL: The only remedy for a bad cache is a redeploy.
Scoring: 16 items total. 14+ passes — ship it. 10–13 — ship behind a flag with per-route monitoring. Under 10 — you have a correctness risk, not a cost problem.
Key takeaways
- Token spend usually leaks through redundancy, not pricing; duplicate execution and burst stampedes are the two dominant patterns.
- Deterministic request identity is the prerequisite — canonical serialization plus a hash over every sampling parameter, schema, tenant scope, and prompt version.
- Provider prefix caching and application-level dedupe solve different problems; you generally need both.
- In-flight coalescing is where the dramatic wins live, because bursts are concurrent by definition.
- Cache safety rules (no errors, no truncated output, tenant isolation, kill switch) matter more than hit rate.
Next steps
- Instrument the current duplicate rate on your three highest-volume LLM routes for one week before changing anything.
- Implement canonical hashing first, then caching, then coalescing — in that order, each behind a flag.
- Write the failure-mode tests before the feature: stale prompt, cross-tenant join, upstream 429, hung stream.
- Re-run the cost report after two weeks and compare estimated spend avoided against the dashboard, not against the invoice alone.