AI news
A practitioner essay published on Dev.to makes a distinction that most AI-coding headlines blur: producing an implementation, exploring a design, and deciding whether a system solves the right problem are three different activities. Automating the first does not settle the other two. The author's position is that agents can take on more implementation work and assist with analysis, design and testing, while engineers remain accountable for what gets built and what evidence is sufficient to accept it.
That is a less dramatic claim than "AI replaced our developers," and a more useful one. It reframes the debate from headcount to decision rights.
What the argument actually says
The essay separates the software lifecycle into layers. At the bottom sits implementation: turning a defined change into working code. This is where coding agents have improved fastest and where the leverage is most visible. Above it sit design exploration and problem framing — choosing an approach, understanding constraints, and confirming that the thing being built is the thing that should be built. Above that sits acceptance: the judgment that a result is correct, safe and ready.
Figure: Editorial context image from the source page (preview only; rights remain with the publisher) · Credit / further reading: dev.to
The author's point is not that agents are bad at the upper layers. It is that assistance there is advisory, not authoritative. An agent can propose three architectures; it cannot own the consequences of picking one. It can generate a test suite; it cannot decide that the suite is the right proof.
This matters because the industry keeps collapsing the layers into a single productivity metric — lines shipped, tickets closed, pull requests merged. Those metrics measure the bottom layer and are blind to the two above it.
Why builders should care
For teams already running agents in the loop, the practical effect is a shift in where engineering hours go. Less time is spent typing boilerplate and wiring obvious glue code. More time goes into specifying intent precisely, reviewing generated output critically, and building the harness that tells you whether any of it is correct.
That harness is the actual bottleneck. If an agent can produce five candidate implementations in the time a human produced one, then review capacity, not generation capacity, sets your throughput. Teams that scale generation without scaling review and verification simply accumulate unreviewed surface area.
The essay also implies a change in what seniority means. The scarce skill is no longer fluent recall of syntax or APIs — agents have that. The scarce skill is knowing which questions to ask before code exists, and knowing what a trustworthy answer looks like afterward. That is closer to systems engineering than to programming.
The evidence question is the real dividing line
Most of the disagreement about AI-assisted development is really a disagreement about acceptance criteria. If your definition of "done" is that the code compiles and the existing tests pass, agents look transformative. If your definition includes failure modes, observability, security posture, data migration risk and operational cost, the agent's contribution shrinks to one input among several.
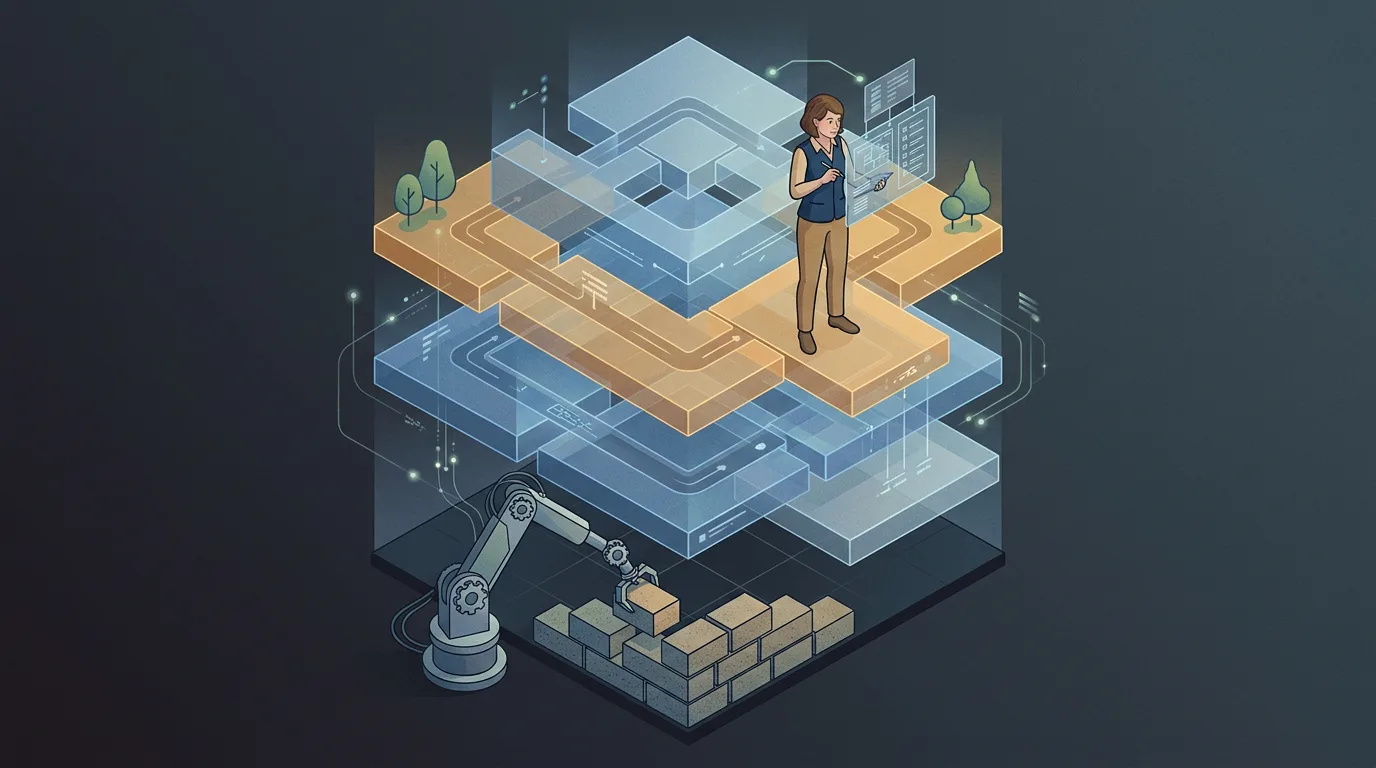
Figure: HEXOPS original illustration inspired by the topic (not a copy of the source article imagery) · Credit / further reading: dev.to
This is why the same tool can feel like a superpower to one team and a liability to another. The tool is constant; the evidentiary bar is not. Organizations with weak verification get faster at producing things they cannot confirm. Organizations with strong verification get faster at producing things they can.
A practical corollary: the more code an agent writes, the more valuable the surrounding machinery becomes — type systems, contract tests, deterministic CI, reproducible environments, staged rollouts. None of that is new. All of it becomes load-bearing when the volume of generated change rises.
What to watch next
The next phase of this debate will not be about whether agents can write code — that argument is largely settled in favor of "yes, increasingly." It will be about ownership. Watch for three signals: how teams redefine review load and split it between human and automated checks; whether job descriptions start naming verification and specification skills alongside implementation skills; and whether acceptance criteria get written down explicitly enough to be checked by anything other than a person's intuition.
Watch also for the failure pattern. The most likely near-term incident is not a model writing broken syntax, but a team accepting a plausible-looking change because nobody retained the context to judge it. That is an organizational gap wearing a technical costume.
The essay's closing position is worth restating plainly: agents can do more of the building, and engineers still have to engineer the system. The code was never the whole job.
Key takeaways
- Implementation, design exploration and acceptance are distinct activities; automating one does not automate the others.
- Coding agents shift engineering effort from typing code toward specifying intent and verifying outcomes.
- When generation outpaces review, review capacity becomes the binding constraint on delivery.
- The same agent tool produces different results across teams because the evidentiary bar for "done" differs.
- Verification infrastructure — types, contract tests, reproducible CI, staged rollouts — becomes more valuable as generated volume rises.
Next steps
- Write down your acceptance criteria explicitly, then ask whether a new team member (or an agent) could check them without asking you.
- Measure review latency and review depth alongside merge volume; treat them as first-class delivery metrics.
- Invest in the harness before scaling generation: contract tests, deterministic builds, and rollback paths.
- Separate "agent proposed" from "human accepted" in your audit trail so ownership is always traceable.
- Revisit role definitions to reflect specification and verification as core engineering skills.