Comparison
Three announcements arrived in the same news cycle, and it is tempting to read them as a single story about model progress. They are not. Anthropic's verification work, OpenAI's image release, and Kimi's reported weight drop address three different layers of the stack — trust, output, and ownership — and each one implies a different buying decision.
The Proof Layer, the Image Layer, and the Weight Layer
Figure: Editorial context image from the source page (preview only; rights remain with the publisher) · Credit / further reading: dev.to
Proof layer: who answered, and can you demonstrate it?
The most consequential of the three is also the least visual. As reported, Anthropic described a system that attaches cryptographic evidence to model output, so that a downstream party can verify which model produced a given response rather than taking an API log's word for it.
Read that carefully. It is a claim about attribution, not about accuracy. A verified answer can still be wrong. What changes is the audit trail: procurement teams, regulators, and enterprise buyers can, in principle, check that the model they contracted is the model that ran — which matters in routing setups where a gateway may silently fall back to a cheaper model, or where a reseller's branding hides the underlying weights.
For anyone selling AI into finance, health, or the public sector, this is a compliance artifact, not a feature. For everyone else, it is insurance you may not need yet.
Image layer: a better output, same ownership question
OpenAI's reported Images 2.6 release sits at the opposite end of the abstraction ladder. It is an output-quality story: a stronger rendering and editing stack available through a hosted API, with no new rights or governance attached.
The practical question for a storefront or content team is not whether the images look better — they usually do — but whether marginal quality is worth the per-call cost and the continuing dependency on a single hosted vendor for a core creative asset pipeline.
Weight layer: capability you can hold, if you can hold it
Kimi's reported 2.8-trillion-parameter weight release is the loudest of the three and the easiest to over-read. Open weights change the economics and the risk profile: you can self-host, fine-tune, and keep data inside your own perimeter, but you also inherit the serving bill, the evaluation burden, and the licence review.
Treat the parameter count as a headline, not a specification. What matters is whether the weights are actually downloadable at a size your team can serve, under a licence your legal team accepts, with benchmark parity on your own task set.
Comparison Criteria
| Option | What you actually get | Where it fits | Main trade-off |
|---|---|---|---|
| Provenance / verification layer (Anthropic, as reported) | Cryptographic evidence tying a response to a specific model | Regulated industries, resold AI, multi-model gateways, audit-heavy procurement | Adds engineering surface; proves attribution only, not correctness |
| Hosted image stack (OpenAI Images 2.6, as reported) | Higher-fidelity generation and editing via API | E-commerce creative, marketing, rapid prototyping, small design teams | Per-call cost and single-vendor dependency; rights still governed by terms of service |
| Open weights (Kimi, reported at 2.8T) | Downloadable model you can host, tune, and isolate | Data-residency constraints, high-volume steady workloads, research, cost engineering at scale | You own the serving cost, the evaluation, and the licence risk |
Scoring the dimensions that actually decide it
| Dimension | Proof layer | Image stack | Open weights |
|---|---|---|---|
| Verifiability of what ran | Strong | Weak (vendor log only) | Strong (you hold the artifact) |
| Out-of-the-box output quality | Not applicable | Strong | Task-dependent |
| Data residency control | Moderate | Vendor-dependent | Strong |
| Time to first value | Weeks | Days | Weeks to months |
| Ongoing operational load | Low to moderate | Very low | High |
| Licence and legal exposure | Low | Moderate | Highest — must be reviewed |
| Lock-in risk | Low (portable concept) | High | Very low |
Choosing by Scenario
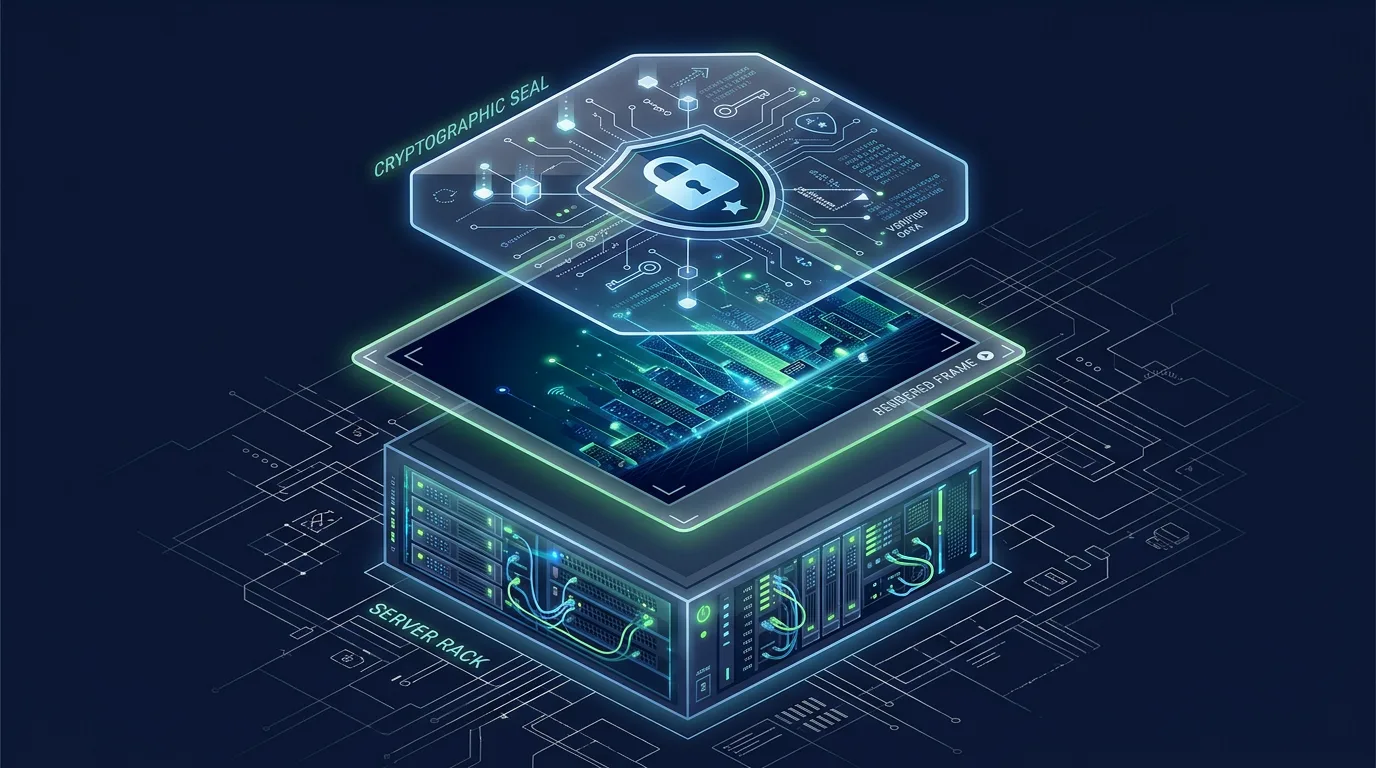
Figure: HEXOPS original illustration inspired by the topic (not a copy of the source article imagery) · Credit / further reading: dev.to
You are selling AI into a regulated buyer. Start with the proof layer. Verification is not a differentiator you can charge for on day one, but it is increasingly a checkbox in security reviews. Combine it with a hosted model for output quality and keep the evidence chain at your gateway so every downstream call is covered.
You run a storefront or a content pipeline. Take the hosted image stack, and hedge. Keep prompts and asset metadata in a vendor-neutral format so a second provider can be swapped in during a pricing change or a quality regression. The cost that hurts is not per-image — it is a rewrite under deadline.
You have data-residency constraints or a very predictable, high-volume workload. Open weights are the structurally correct answer. Model the total cost honestly: GPUs or reserved capacity, evaluation harness, safety filtering, and on-call. Self-hosting is rarely cheaper at low volume and rarely more expensive at high sustained volume — the crossover point is the whole question.
You are a small team with no platform engineers. Buy hosted, both layers. The provenance conversation can wait until a customer asks; the image quality conversation cannot.
You are a platform team serving many internal products. Do all three, but in the right order: verification at the routing layer, images as a managed vendor dependency, and open weights only for the two or three workloads where volume or residency justify the operational tax.
A note on stacking them
The three are not competitors. A defensible architecture routes by task, verifies at the edge, and keeps one open-weight model in reserve for the workloads that must never leave your perimeter. The mistake is treating any one of them as a strategy rather than a component.
Key Takeaways
- This week's news moved three separate layers: attribution, output quality, and ownership. They answer different questions and have different budgets.
- Provenance proves which model answered, not whether the answer is right. Do not let it stand in for evaluation.
- A stronger hosted image model is a quality upgrade you rent, not an asset you own. Design for substitution.
- Open weights shift cost from per-token fees to engineering headcount. That trade only pays off at scale or under residency constraints.
- Parameter counts are marketing; licence terms, servability, and task-level benchmarks are the real specification.
Next Steps
- Write down which of the three layers your current pain actually sits in — a security review question, an output quality gap, or a cost or residency ceiling.
- Run a two-week bake-off on your own data before committing. Vendor benchmarks rarely survive contact with your edge cases.
- For provenance: audit every hop between your app and the model, including gateways and fallbacks.
- For images: store prompts and outputs in a portable schema so migration is a config change, not a project.
- For open weights: get legal sign-off on the licence before you get GPU quotes.
Sources
- Original tip and coverage roundup: Anthropic Proves LLM Outputs, OpenAI Ships Images 2.6, Kimi Drops 2.8T Weights
All product details above are as reported in the source and should be verified against official documentation and licence terms before procurement.