GEO
An AI agent can run a shell command, patch a file, and commit the result. What it cannot do is click a button inside the Godot editor. So when the task is to put a game into a specific state—progress/stage = 7, tutorial_done = true, audio/master = 0.42—the agent edits the save file directly. The editor could do the same through a dock, but a terminal cannot see the dock. This is not a Godot problem. It is a machine-first problem, and it is exactly the problem your website now has.
The save-file problem is a machine-first problem
Figure: Editorial context image from the source page (preview only; rights remain with the publisher) · Credit / further reading: dev.to
The naive approach is json.load → change one value → json.dump. On a real Godot save, that quietly changes data you did not ask to change. Numbers may round-trip differently. Key order may shift. Unicode escapes may be rewritten. Defaults, hidden fields, and type expectations may be lost. The editor preserves invariants because it knows the schema; a generic JSON tool does not.
That is the core lesson for GEO: when an AI agent consumes your content, it is not browsing your UI. It is reading a raw representation and trying to preserve your meaning without knowing your invariants. If your pages depend on layout, client-side state, tabs, hover text, or implicit defaults, the machine sees a different document than your human visitor does. The question is not whether agents will parse you. The question is what survives the parse.
Why this matters for search and GEO
Classic SEO asks whether crawlers can fetch, render, and index a page. GEO asks a harder question: can a model extract a stable fact, attribute it correctly, and cite it without mangling the source? Agents do not click. They fetch HTML, strip tags, chunk text, call tools, and synthesize. Every one of those steps is a lossy transformation unless you design for it.
What breaks when an AI reads your site
- Types and numbers. Prices, dates, versions, ratings, and quantities often become strings or floats. A page that says
$19.00may be quoted as19or1900. Structured data reduces this ambiguity. - Structure. Headings, lists, and tables collapse into plain text. A comparison table becomes a paragraph, and the relationship between columns disappears.
- State. Content behind JavaScript, cookies, geolocation, or A/B tests may never appear in the fetched representation. If the fact only exists after a click, an agent may never see it.
- Identity. Canonical URLs, slugs, product names, and entity identifiers drift across pages. Agents cite what they can resolve, and ambiguous identities produce ambiguous citations.
- Provenance. Deep links to anchors, query strings, and session-specific URLs are unstable. A citation that points to yesterday's A/B variant is not a citation you can audit.
Structured content is the invariant layer
The editor in the Godot story preserves schema because it understands the file. On the web, the closest equivalent is structured content: server-rendered HTML, schema.org and JSON-LD, stable IDs, explicit dates, canonical URLs, and clean markdown mirrors. These are not decorations for rich results. They are the invariants that let a machine reconstruct your meaning without guessing.
A practical test is to view your page as plain text. If the facts disappear, the agent will not find them. If the facts remain but the relationships vanish, the agent may misquote them. If the facts survive with their source and date attached, you have something citeable.
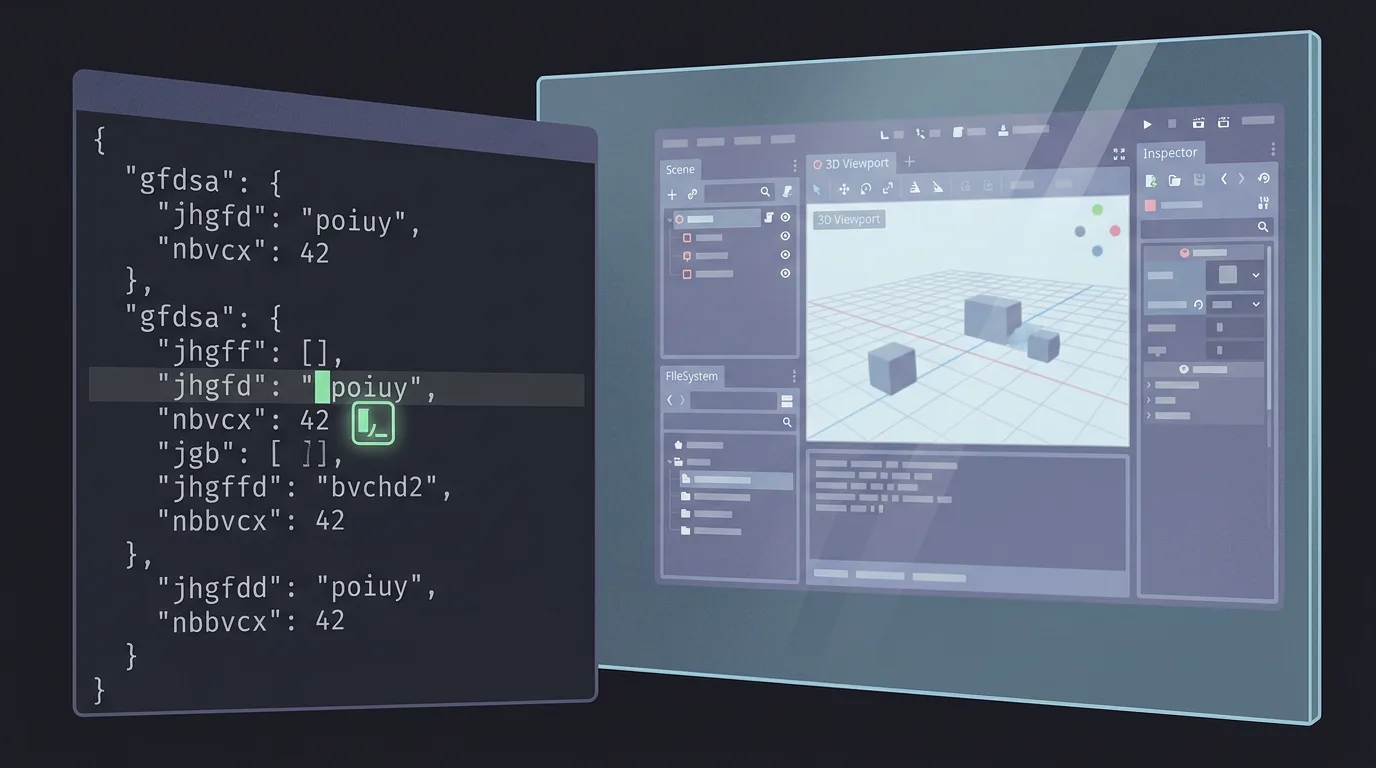
Figure: HEXOPS original illustration inspired by the topic (not a copy of the source article imagery) · Credit / further reading: dev.to
llms.txt is the dock, not the save file
llms.txt is useful because it gives models an explicit map of what matters on your site: canonical pages, summaries, preferred entry points, and licensing. But it is a dock, not the save file. It does not replace well-structured pages, and it cannot compensate for content that only exists after a client-side render. Treat it as a maintained index: version it, review it when URLs change, and make sure every line resolves to a stable page.
The same logic applies to sitemaps, RSS, OpenGraph, and content negotiation. Each is a machine-readable promise. If the promise drifts from the page, agents will trust one representation and cite another.
AI citations reward stable, extractable facts
Models cite what they can extract with confidence. That favors pages with clear headings, short declarative sentences, named sources, publication dates, and canonical URLs. It penalizes pages where the key fact is buried in a video, locked behind a bot wall, or split across ten slides.
This does not mean writing for robots. It means writing so that the human meaning survives machine extraction. A sentence like “According to the 2024 report, adoption rose 18% year over year” is both readable and citeable. A dashboard where the same number appears only after three filters is neither.
Designing for agents without breaking humans
You do not need a separate agent-only website. You need one source of truth with multiple faithful representations: HTML for browsers, structured data for parsers, markdown for retrieval, and llms.txt for orientation. Keep bot access deliberate—blocking AI crawlers may protect content, but it also removes you from the citation layer. Measure what agents actually fetch, not just what browsers render.
Key takeaways
- Agents consume raw representations, not your UI. Structure is an API.
- Preserve invariants: canonical IDs, types, dates, provenance, and stable anchors.
- Publish
llms.txtas a map, not a substitute for structured pages. - Make facts extractable and citeable with clear headings, sources, and dates.
- Test your site as plain text and as an agent, not only as a browser.
Next steps
- Audit five key pages as plain text and note which facts disappear.
- Add JSON-LD and canonical URLs to every page that should be cited.
- Publish a reviewed
llms.txtand a markdown mirror for core content. - Decide your AI crawler policy explicitly and document it.
- Track AI citations and fix the pages where attribution is unstable.